Build Reliable Data Foundations for Analytics, Applications and AI
Design scalable data pipelines, cloud data platforms and real-time data systems that turn fragmented source data into trusted, usable information.
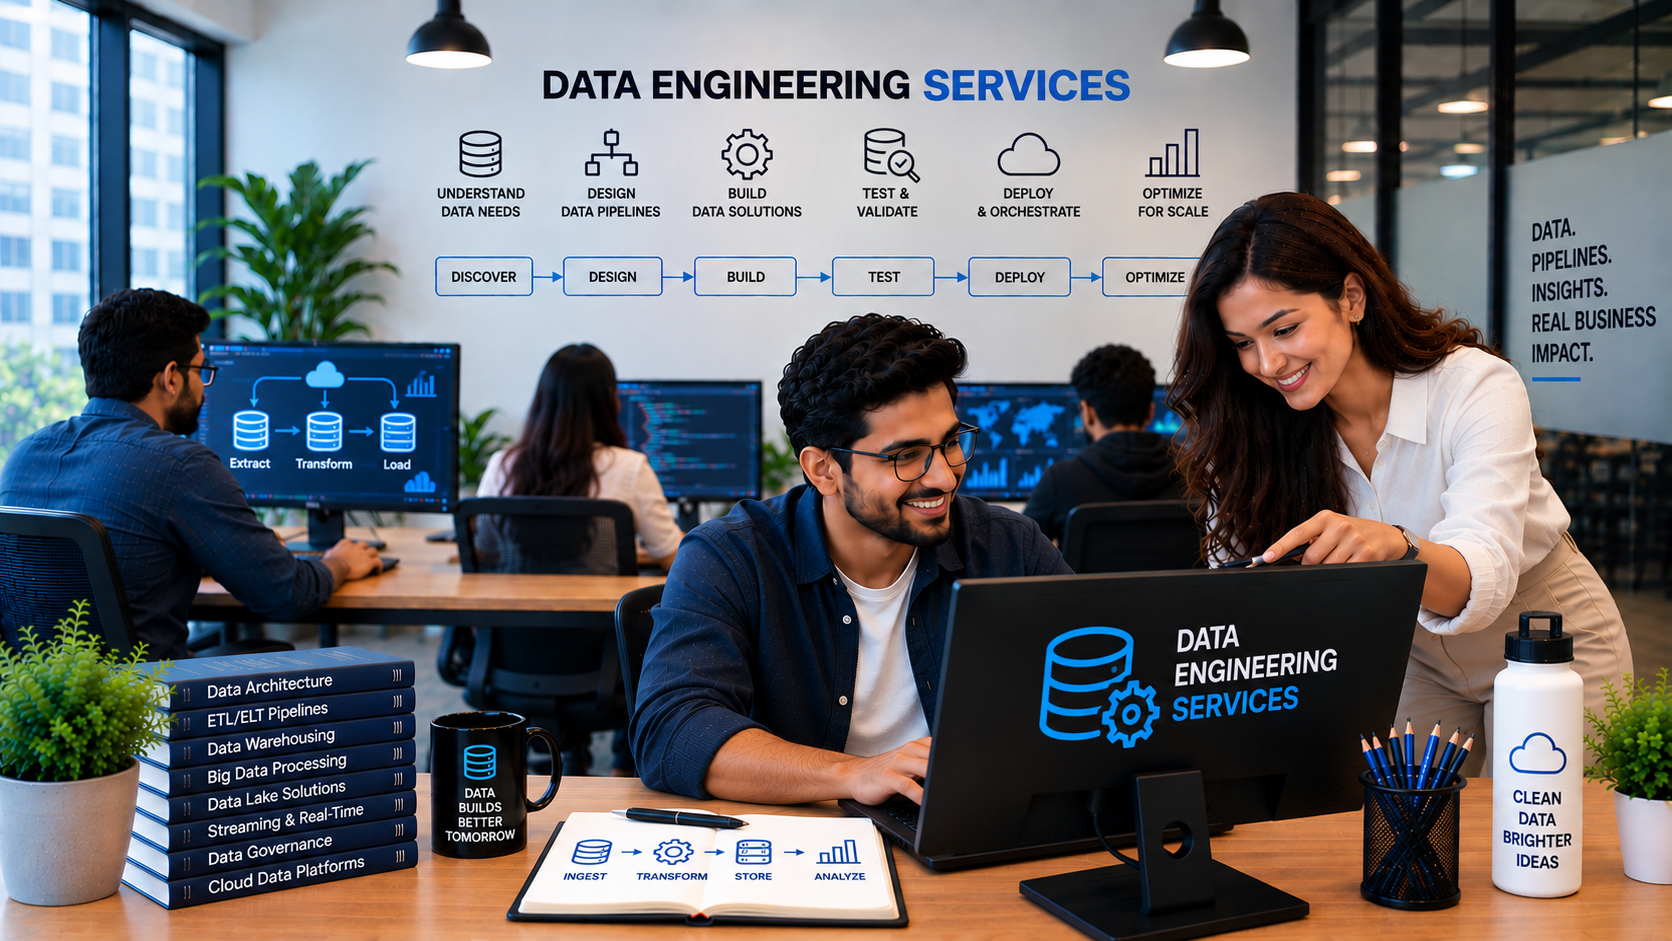
Turn Fragmented Data Into a Foundation Your Business Can Build On
Connect, transform, validate and deliver data around the downstream outcome your business needs.
Reliable data engineering begins with the consumers of the data, including applications, analytics, operational teams and AI systems. We design ingestion, transformation, quality and delivery around those downstream requirements so the platform solves a business need rather than only moving records between systems.
Three benefits.
Reliable Data Pipelines
Platforms Built to Evolve
Data for Analytics & AI
Data Engineering Across the Modern Data Lifecycle
Data Pipelines
Ingestion and transformation pipelines across source systems.
Cloud Data Platforms
Scalable foundations for analytics, applications and AI.
Data Warehouses & Lakehouses
Governed analytical storage and transformation.
Real-Time Data Systems
Streaming and event-driven operational data.
Data Integration Layers
Connect APIs, databases, SaaS and files.
AI Data Foundations
Prepare structured and unstructured data for RAG and AI.
Data Pipeline Development
Move Data Reliably From Source to Consumer.
A production data pipeline must handle more than the happy path. We design source ingestion, schema change, transformation, orchestration, validation, retries and monitoring together so teams can trust both the data and the process that delivers it.
Source Ingestion
Schema Handling
Transformation
Orchestration
Validation
Failure Handling
Core Data Engineering Capabilities
Capability
Source Ingestion
Supporting copy
Connect data sources
Capability
ETL / ELT
Supporting copy
Extract, transform and load
Capability
Data Transformation
Supporting copy
Clean and enrich
Capability
Data Modeling
Supporting copy
Organize data for consumers
Capability
Batch Processing
Supporting copy
Process scheduled workloads
Capability
Stream Processing
Supporting copy
Handle continuous events
Capability
Workflow Orchestration
Supporting copy
Coordinate dependencies
Capability
Data Quality
Supporting copy
Validate critical data
Capability
Schema Management
Supporting copy
Handle structural change
Capability
Lineage
Supporting copy
Track data movement
Capability
Data Observability
Supporting copy
Monitor freshness and failures
Capability
Data APIs / Serving
Supporting copy
Expose data to applications
How We Build Data Platforms
Discover
Inventory sources, consumers, volume, latency and quality issues.
Architect
Define ingestion, storage, transformation, security and operating model.
Build Pipelines
Develop connectors, ETL/ELT, workflows and validation.
Validate
Test completeness, logic, performance and reconciliation.
Deploy & Observe
Release with orchestration, monitoring, lineage and alerts.
Evolve
Add sources, optimize cost/performance and support new consumers.
Build a Reliable Data Foundation
Data Engineering Technology
5.0 REVIEWS
The technology stack depends on source systems, data volume, latency, cloud environment and downstream consumers. We favor maintainable patterns and observable pipelines over unnecessary platform complexity, while leaving room for the architecture to evolve.
Languages
Databases
Cloud
Streaming / Events
Infrastructure
Observability
Build for Batch, Streaming and Legacy Transformation
ETL
Transform before loading where that pattern fits.
ELT
Transform inside modern analytical platforms.
Streaming
Process events continuously or near real time.
CDC
Capture source-system changes incrementally.
Modernization
Rework legacy data flows without losing business logic.
AI-Ready Data
Prepare reusable structured and unstructured foundations.
Connect With the Systems Your Business Already Uses
Databases
PostgreSQL | MySQL | SQL Server | MongoDB
SaaS / ERP / CRM
Enterprise systems through APIs/connectors
Files
CSV | object storage | document sources
APIs
REST | webhooks | third-party data
Events
Queues | event streams | telemetry
Consumers
BI | applications | ML | RAG | AI agents
Engagement Model
Protect Data Through the Engineering Lifecycle
Apply access, reliability and recovery controls according to the data's criticality.
Access Control
Restrict platforms and datasets appropriately.
Data Protection
Secure data in transit and at rest where applicable.
Secrets
Protect database/API credentials.
Validation
Detect missing, malformed or unexpected data.
Audit / Lineage
Track important movement and transformations.
Recovery
Design backup, replay and recovery around business requirements.
Data platforms often connect systems with different access and retention requirements. We design service credentials, platform permissions, validation, lineage and recovery controls according to the sensitivity and operational importance of the data being processed.
Why Choose Virtual Coders for Data Engineering?

"Game-Changing Custom SaaS Solutions – Highly Recommended! Working with Virtual Coders to develop our custom SaaS platform was transformative. Their team grasped our unique needs and delivered a robust solution, greatly enhancing our operations. Their attention to detail and proactive communication made the process smooth and enjoyable. Highly recommended for Australian companies seeking to enhance their software solutions!"
Rick Giesel
Owner, ICT
Why Choose Virtual Coders for Data Engineering?
✓Full-stack understanding of applications and data consumers.
✓API and enterprise integration experience.
✓Cloud and DevOps capability around production data systems.
✓AI engineering knowledge for RAG and agent data requirements.
✓Product thinking focused on the decision or workflow the data supports.
Frequently Asked Questions

Planning a New Data Platform or Modernization?
They design and build systems that collect, transform, validate, store and deliver data for analytics, applications and AI.
It creates repeatable flows that move data from source systems through ingestion, transformation and validation into usable destinations.
ETL transforms before loading; ELT loads first and transforms within the destination. The right pattern depends on architecture and requirements.
Yes. Event streaming, queues and Change Data Capture can support lower-latency data movement where required.
It builds shared storage, transformation, orchestration, quality and access layers for multiple data consumers.
It can include migration, schema redesign, pipeline rebuilding, cloud adoption, validation and staged retirement of legacy workloads.
It makes enterprise data accessible, current, contextualized and reusable for RAG, copilots, agents and machine-learning applications.
Yes, engagements can include freshness, completeness, schema checks, reconciliation, pipeline monitoring and alerts.
SEND US A MESSAGE.

READY TO ACCELERATE YOUR TECH JOURNEY?
Partner with our expert engineers to transform your ideas into scalable, high-performance solutions tailored to your business needs.
OUR OFFICES
India
E-414 to 416, Ganesh Glory 11, Jagatpur Road, Nr. BSNL Office, off. S.G. Highway, Jagatpur, Ahmedabad, Gujarat - 382470
Australia
18, Giancarlo Crescent, Doolandella-4077, QLD, Australia
Canada
20 Meadowglen Pl, Toronto, ON M1H 2Y5